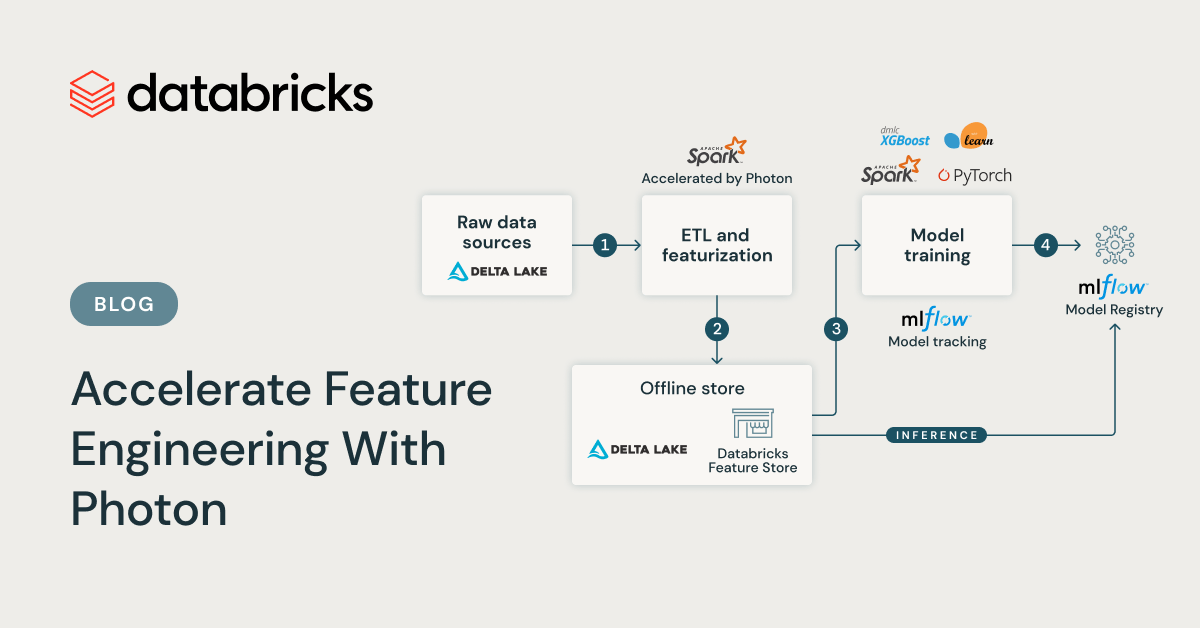
Accelerate Feature Engineering With Photon
Training a high-quality machine learning model requires careful data and feature preparation. To fully utilize raw data stored as tables in Databricks, running ETL pipelines and feature engineering may be required to transform the raw data into helpful feature tables. If your table is large, this step could be very time-consuming. We are excited to […]
Continue Reading